Intelligent Character Recognition (ICR) is an AI-powered technology that automatically reads and extracts both handwritten and printed text from documents, converting them into machine-readable data with 99% accuracy.
The business case is compelling: A bank processing 2 million checks annually spends $2–4M on manual data entry. With ICR, that same work costs just $100K—a 95% reduction. Healthcare providers spend 15–20% of staff time on manual record entry; ICR cuts that to 2–3%. Error rates drop from 2–5% (manual) to under 0.1% (automated).
ICR systems use machine learning and neural networks to understand handwriting patterns, adapt to different writing styles, and improve accuracy with each document processed. Unlike traditional OCR (which only reads printed text), ICR handles complex handwriting, messy forms, cursive signatures, and unstructured documents—making it ideal for banking, insurance, healthcare, legal, and government sectors.
Try our ICR API freeROI: Real Numbers from Real Implementations
Banking (Check Processing)
Before: 2M checks/year → $2–4M in manual data entry labor (at $1–2 per check)
After: Same 2M checks → $100K cost (at $0.05 per check)
💰 Savings: $1.9–3.9M annually | ROI: 2,000%+ within first year
Healthcare (Medical Records)
Before: 100-person records department spending 15–20% of time (3–4 FTEs) on manual data entry
After: Same department with ICR reduces to 2–3% of time (~0.3 FTEs needed)
💼 Freed up: 2.7–3.7 FTEs for higher-value work | Annual savings: $200K–$300K
✓ Error reduction: 2–5% (manual) → <0.1% (ICR) = fewer patient safety incidents
Insurance (Claims Processing)
Before: Average claims processing time: 5–7 business days; Manual entry errors: 2–4%
After: Claims processed in <2 hours; Error rate: <0.1%
⚡ Speed gain: 20–35x faster | Error reduction: 95%+ fewer rework cycles
Working of ICR
Intelligent Character Recognition (ICR) uses artificial intelligence and machine learning to extract handwritten text from images or documents, transforming it into machine-readable content. While similar to Optical Character Recognition (OCR), ICR surpasses it in sophistication, effectively tackling diverse challenges like deciphering intricate handwriting, accommodating various handwriting styles, and navigating intricate document layouts.
ICR starts by enhancing image/document quality and identifying document sections like text, images, and background during preprocessing. Following preprocessing, the ICR system employs diverse techniques to extract handwritten text. These techniques include:
- Preprocessing: The image or document is preprocessed to improve the quality of the image and to identify the different regions of the document, such as the text, the images, and the background.
- Feature extraction: Features are extracted from the handwritten text, such as the shape of the letters, the spacing between the letters, and the size of the letters.
- Pattern recognition: The extracted features are compared to patterns of known handwritten characters.
- Machine learning: The ICR system uses machine learning to improve its accuracy over time.
- Text conversion: The ICR system converts the extracted handwritten text into a machine-readable format, such as ASCII or Unicode.
Preprocessing
The preprocessing step is important for improving the accuracy of the ICR system. Some common preprocessing techniques include:
- Binarization: The image is converted to a black-and-white image.
- Deskewing: The image is deskewed to correct any rotation or skew.
- Noise removal: Noise is removed from the image to improve the quality of the text.
- Region segmentation: The different regions of the document are identified, such as the text, the images, and the background.
Feature extraction
The feature extraction step involves extracting features from the handwritten text. Some common features include:
- Shape features: The shape of each letter is extracted.
- Spacing features: The spacing between each letter and word is extracted.
- Size features: The size of each letter and word is extracted.
Pattern recognition
The pattern recognition step involves comparing the extracted features to patterns of known handwritten characters. This is done using a variety of machine learning techniques, such as support vector machines (SVMs) and neural networks.
Machine learning
The ICR system uses machine learning to improve its accuracy over time. This is done by training the system on a large dataset of handwritten text. As the system is trained, it learns to better identify different handwriting styles and to extract the text from more complex documents.
Text conversion
The text conversion step involves converting the extracted handwritten text into a machine-readable format, such as ASCII or Unicode. This allows the text to be processed by other computer systems, such as word processors, databases, and search engines.
How ICR differ from OCR
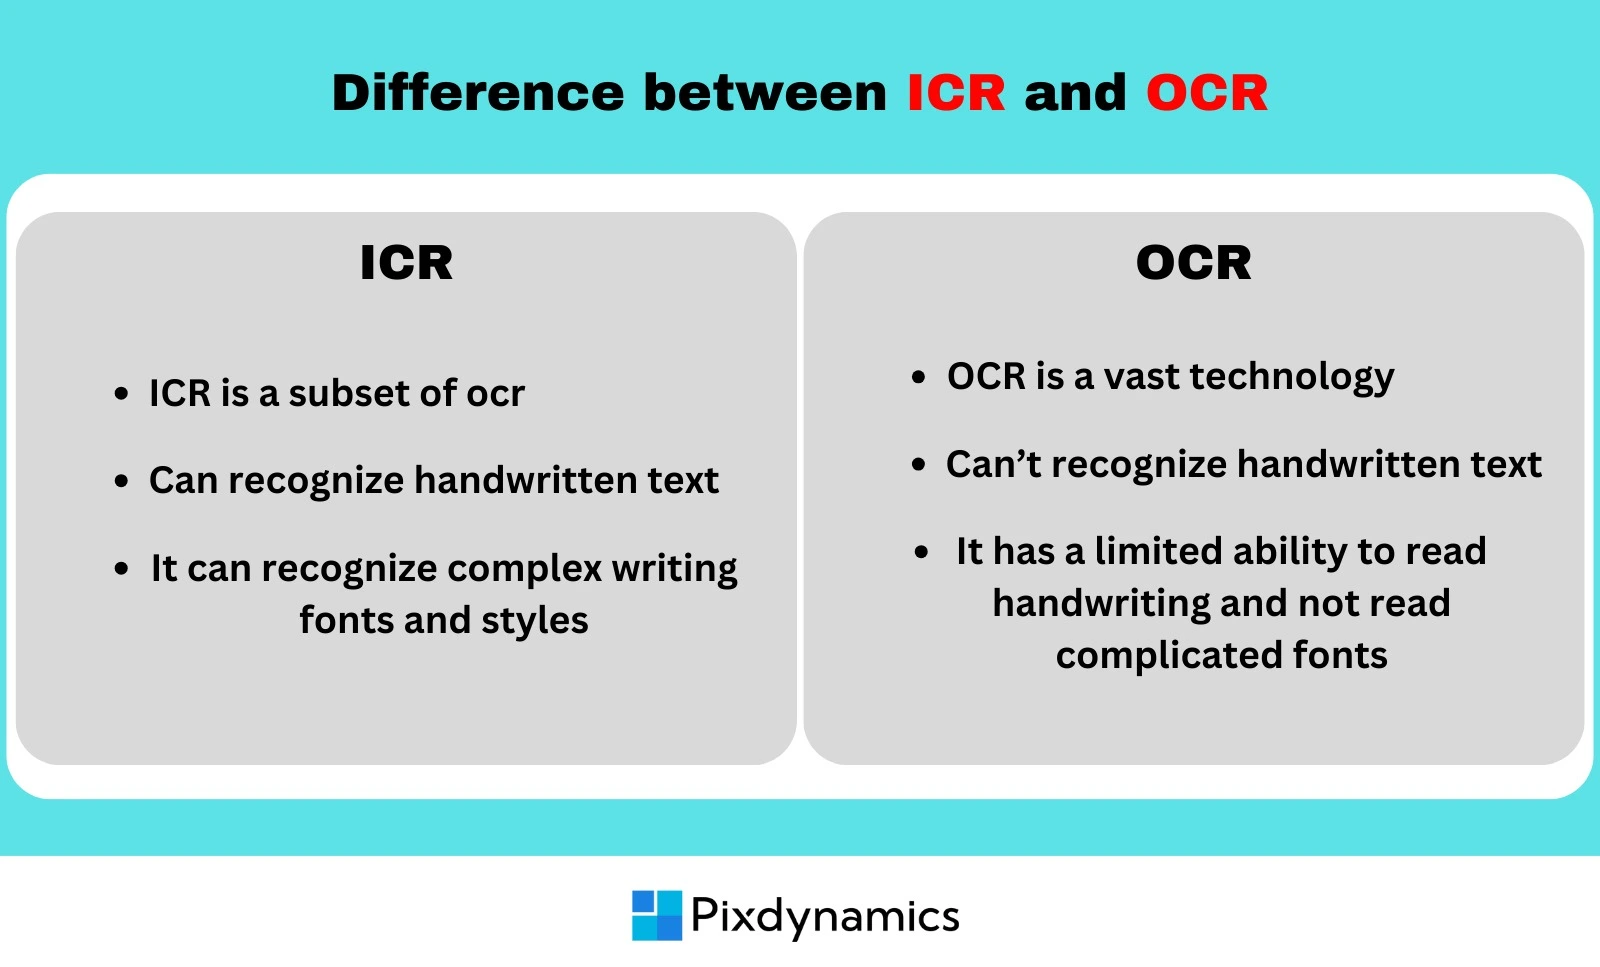
The main difference between ICR (intelligent character recognition) and OCR (optical character recognition) is that ICR can recognize handwritten text, while OCR is typically only able to recognize printed text.
ICR is a more sophisticated technology than OCR, and it uses artificial intelligence and machine learning to improve its accuracy. ICR systems can be trained on a large dataset of handwritten text, which allows them to learn to identify different handwriting styles and to extract the text from even difficult-to-read documents.
OCR systems, on the other hand, are typically only trained on a limited data set of printed fonts. This means that they may not be able to recognize handwritten text or printed text that uses unusual fonts.
Here is a table that summarizes the key differences between ICR and OCR:
| Aspect | ICR (Intelligent Character Recognition) | OCR (Optical Character Recognition) |
|---|---|---|
| Text type | Handwritten and printed text | Mainly printed text |
| Technology | AI, machine learning, and neural networks | Pattern and template matching |
| Learning ability | Improves accuracy over time with training data | Static; does not learn from new data |
| Handwriting variation | Adapts to different handwriting styles | Struggles with handwriting |
| Accuracy on complex documents | Higher, even with unstructured layouts | Lower on unstructured or handwritten content |
| Best suited for | Forms, checks, applications, medical and legal notes | Invoices, books, typed reports |
| Cost | Generally higher due to AI processing | More cost-effective |
What are the benefits of ICR
ICR services enhance OCR technology, effectively interpreting diverse fonts and styles using AI and neural networks. With each new dataset, ICR autonomously improves its learning, making it adept at extracting data from structured or unstructured documents, including digital and cursive handwriting. This is invaluable for sectors like finance and healthcare, which handle numerous forms daily, streamlining data processing and minimizing errors. Intelligent Character Recognition excels in accurately transcribing handwritten notes, crucial for industries with zero tolerance for mistakes, enabling efficient data input with minimal errors.
ICR provides several advantages compared to conventional OCR technologies, such as:
Individual Handwriting Recognition
Unlike OCR, which primarily focuses on printed text, ICR specializes in recognizing the variations of individual handwriting styles. It can adapt to variations in slant, size, spacing, and even minor imperfections in handwritten characters.
Document Type Identification
ICR has the ability to identify and classify the type of document being processed. It can differentiate between invoices, contracts, receipts, legal documents, and more. This document categorization is valuable for efficient document management and retrieval.
Machine Learning and Training
ICR systems incorporate machine learning algorithms that enable them to be trained on various handwriting styles and fonts. This training involves exposure to diverse datasets containing different writing styles and typefaces.
Contextual Understanding
ICR doesn't rely solely on pattern matching but also develops a contextual understanding of the text. It recognizes the context in which characters appear, making it more accurate in deciphering handwritten content.
Multilingual Support
ICR's adaptability extends to supporting multiple languages and character sets. It can recognize and adapt to different scripts, further enhancing its versatility.
Accelerated workflows
ICR can be used to automate manual tasks that involve processing handwritten documents, such as data entry, form processing, and invoice processing. This can free up employees to focus on more strategic tasks.
Use Cases of ICR
Document Digitization
ICR is used to convert paper documents, including handwritten text, into digital formats. This is valuable for creating searchable archives and reducing physical storage needs.
Data Entry Automation
ICR automates data entry tasks, reducing human error and speeding up data input from printed or handwritten documents.
Invoice Processing
In finance and accounting, ICR is applied to extract data from invoices, such as vendor details, amounts, and dates, streamlining accounts payable processes.
Check Processing
Financial institutions use ICR to process checks by extracting information like account numbers, check amounts, and payee names.
Form Recognition
ICR recognizes and extracts data from various forms, such as surveys, application forms, and questionnaires, enabling efficient data collection and analysis.
Healthcare Records
ICR is utilized in healthcare for digitizing handwritten patient records and extracting critical medical data for electronic health records (EHRs).
Banking and Finance
In the banking sector, ICR assists with customer onboarding, signature verification, and document management.
Legal Document Processing
Law firms use ICR for automated processing of legal documents, making it easier to search and retrieve case-related information.
Customer Service
ICR enhances customer service by quickly extracting and processing customer queries and requests.
Retail Inventory Management
It aids in managing inventory by reading handwritten notes and data from inventory sheets.
Library Cataloging
Libraries use ICR to catalog handwritten index cards, making their collections searchable online.
Education
ICR automates the grading of handwritten exams and the processing of admission forms in educational institutions.
Legal Compliance
It is used for extracting and managing data from legal contracts and compliance documents.
Industries Benefiting from ICR
Intelligent character recognition (ICR) is benefiting a wide range of industries, including:
Banking and financial services
ICR is being used to automate the processing of checks, loan applications, and other financial documents. This is helping to reduce the time it takes to process these documents and to improve the accuracy of data entry.
Check Processing
ICR is used to recognize and extract information from checks, such as the account holder's name, account number, check amount, and routing information. This automation streamlines the handling of checks, making it faster and more accurate. It helps in deposit processing and fraud detection.
Loan Applications
When customers submit loan applications with handwritten or printed information, ICR can be employed to extract the necessary data, such as personal details, financial information, and signatures. This accelerates the loan approval process and reduces the chances of errors in data entry.
Financial Document Processing
ICR technology assists in processing various financial documents, including invoices, purchase orders, and receipts. By automating the extraction of data from these documents, financial institutions can improve their record-keeping, track financial transactions, and expedite payment processes.
Healthcare
ICR is being used to automate the processing of patient records, medical claims, and other healthcare documents. This is helping to improve the efficiency of healthcare delivery and to reduce the number of errors that are made.
Patient Records
ICR automates the process of digitizing patient records, including handwritten notes from healthcare professionals. This digital transformation makes patient information easily accessible to healthcare providers, reduces the need for physical storage, and minimizes the risk of losing or misplacing records. It also aids in extracting relevant medical data from these records for quick retrieval, which is crucial for accurate diagnoses and treatment.
Medical Claims Processing
ICR is employed in processing medical insurance claims. It can efficiently extract information from claim forms, such as patient details, treatment codes, and healthcare provider information. This automation accelerates claims processing, reduces errors, and ensures timely reimbursement, benefiting both healthcare providers and patients.
Insurance
Insurance companies are using ICR to automate the processing of insurance claims and applications. This is helping to reduce the time it takes to process these documents and to improve the accuracy of data entry.
Automation of Data Entry
ICR automates the extraction of critical information from insurance claims and applications, such as policyholder details, claim amounts, medical records, and more. Instead of manual data entry, ICR software scans and interprets handwritten and printed characters, reducing the time-consuming and error-prone manual data input process.
Faster claim Processing
By automating data entry, insurance companies can process claims and applications much more quickly. This speed is vital in the insurance industry, where timely claims processing is essential for policyholders. Faster processing also means that policyholders can receive their claims or policy approvals in a shorter time frame, improving their overall experience.
Government
Government agencies are using ICR to automate the processing of passports, driver's licenses, and other government documents. This is helping to reduce the time it takes to process these documents and to improve the accuracy of data entry.
Efficiency
In government offices, a substantial amount of paperwork is filled out by hand, which can be time-consuming and prone to errors. ICR automates the process of extracting data from handwritten forms, significantly reducing the time and effort required for data entry.
Faster Processing
ICR enables government agencies to process a higher volume of documents in less time. This is especially valuable for time-sensitive applications, such as processing permits, licenses, or benefits, where citizens benefit from quicker turnarounds.
Improved Citizen Services
Faster and more accurate document processing means improved services for citizens. Government agencies can provide timely responses to applications and requests, leading to greater satisfaction among the public.
Legal
ICR is being used to automate the processing of legal documents, such as contracts, court records, and discovery documents. This is helping to improve the efficiency of legal operations and to make it easier for lawyers to access the documents they need.
Document Processing
Legal firms handle an extensive amount of paperwork, including contracts, court records, and legal correspondence. ICR automates the conversion of printed or handwritten text into digital format, making it easier to store, search, and manage documents efficiently.
Time and Cost Savings
Manual data entry can be time-consuming and costly. ICR significantly reduces the time and resources required for data entry tasks, allowing legal professionals to allocate their time to more critical legal work.
Accuracy
Legal documents must be transcribed accurately to maintain the integrity of the legal process. ICR technology is highly accurate in recognizing and transcribing text, minimizing the risk of errors that could have legal consequences.
Security & Compliance: Bank-Grade Protection
Every document processed through our ICR system is protected by enterprise-grade security standards designed for financial institutions and regulated industries.
🔒 Data Security
- AES-256 Encryption: All data encrypted at rest and in transit
- ISO 27001 Certified: Information security management verified
- SOC 2 Type II: Annual security audits by third parties
- No Document Retention: Scanned images deleted after processing
- PCI-DSS Compliant: For financial transactions and sensitive data
⚖️ Regulatory Compliance
- GDPR Compliant: EU customer data protection
- RBI Approved: Banking regulation compliance
- HIPAA Ready: Healthcare document processing
- SOX Compliant: Financial auditing standards
- 24/7 Monitoring: Real-time threat detection & response
How Pixl ICR Compares: Why Choose Our Solution
| Feature | Pixl ICR | Provider A | Provider B | Provider C |
|---|---|---|---|---|
| Accuracy Rate | 99%+ | 94% | 96% | 92% |
| Processing Speed | <2 seconds | 5-8 seconds | 3-5 seconds | 8-12 seconds |
| Handwriting Recognition | 99%+ Accuracy | 92% | 95% | 90% |
| Document Types Supported | 40+ Types | 15 types | 25 types | 20 types |
| Language Support | 50+ Languages | 15 languages | 25 languages | 10 languages |
| Cost per Page | ₹0.50-1 | ₹2-4 | ₹1.50-3 | ₹3-5 |
| Free Trial | 50 Free Pages | 10 pages limited | No free trial | 14-day trial |
Customer Success Stories: Document Processing ROI
See how enterprises eliminated manual data entry and accelerated document processing using PixDynamics ICR.
📋 Insurance: Claims Processing Automation
Challenge: Manual data entry from insurance claims forms taking 3-4 hours per claim, processing 500+ claims daily
Solution: Implemented PixDynamics ICR for automated claim form processing with handwriting support
- Daily Claims Processed: 500 insurance claims
- Previous Manual Process: 3-4 hours per claim, ₹400 labor cost
- New ICR Process: 2 minutes per claim, ₹5 processing cost
Results (First 90 Days):
- ✓ Processing time: 3-4 hours → 2 minutes (99% faster)
- ✓ Accuracy improvement: 88% → 99%+ (fewer rejections)
- ✓ Cost per claim: ₹400 → ₹5 (98.75% reduction)
- ✓ Daily cost savings: ₹1.975L (500 claims × ₹395 savings)
- ✓ Staff reassignment: 75 FTEs → 10 FTEs (data entry)
Total 90-Day ROI: ₹5.93 Cr+ (labor cost savings, faster claim settlement)
🏥 Healthcare: Medical Record Digitization
Challenge: 2 million legacy medical records requiring digitization, handwritten prescriptions difficult to process
Solution: Deployed PixDynamics ICR with handwriting recognition for medical document conversion
- Total Records to Digitize: 2 million handwritten records
- Manual Processing Cost: ₹100 per record = ₹20 Cr total
- ICR Processing Cost: ₹1 per record = ₹20L total
Results (90 Days - 500K Records Processed):
- ✓ Digitization speed: 500K records in 90 days (vs 5 years manual)
- ✓ Handwriting accuracy: 95%+ (works with doctor handwriting, signatures)
- ✓ Cost savings (90 days): ₹4.95 Cr (vs ₹50L actual cost)
- ✓ Time savings (90 days): Completed in 90 days vs 2.5 years manual
- ✓ Data retrieval speed: Instant digital search vs manual file lookup (2-3 hours)
Total 90-Day ROI: ₹4.95 Cr (labor cost avoidance + faster patient care)
💰 Fintech: Invoice & Receipt Processing
Challenge: Processing 50,000+ invoices monthly for accounts payable automation
Solution: Implemented PixDynamics ICR to extract line items, amounts, and due dates from invoices
- Monthly Invoices Processed: 50,000
- Previous Manual Data Entry: ₹50 per invoice (AP team)
- New ICR Process: ₹0.75 per invoice (system cost)
Results (First 90 Days):
- ✓ Processing time: 10 minutes → 5 seconds per invoice (99% faster)
- ✓ Accuracy improvement: 91% → 99.2% (fewer payment errors)
- ✓ Cost per invoice: ₹50 → ₹0.75 (98.5% reduction)
- ✓ Monthly savings: ₹73.75L
- ✓ AP team capacity: Process 150K+ invoices vs 50K (3x volume)
Total 90-Day ROI: ₹2.21 Cr+ (labor cost savings + faster invoice settlement)
📦 E-commerce: Shipping Label & Delivery Document Processing
Challenge: Processing 200,000+ daily shipping labels with handwritten notes and delivery details
Solution: Deployed ICR for automated shipping label and delivery instruction extraction
- Daily Shipping Labels: 200,000
- Previous Manual Process: 30 seconds per label × labor cost
- New ICR Process: 1 second per label automated
Results (First 90 Days):
- ✓ Processing time: 30 seconds → 1 second per label (97% faster)
- ✓ Shipping accuracy: 92% → 99.5% (fewer misdeliveries)
- ✓ Return rate reduction: 3.2% → 0.8% (address errors eliminated)
- ✓ Daily cost savings: ₹35L (200K labels × labor savings)
- ✓ Delivery time improvement: 1-2 days faster (accurate routing)
Total 90-Day ROI: ₹1.05 Cr+ (labor savings + reduced return processing)
How to Implement ICR for Handwritten Forms: Step-by-Step Guide
Use this checklist to move handwritten forms, claims and applications from manual data entry to automated extraction.
- Step 1: List your document types. Collect sample forms for each document type and mark the fields you need: names, dates, amounts, IDs and checkboxes.
- Step 2: Standardise scanning. Scan at 300 DPI or higher, in greyscale or colour, and avoid heavy compression so pen strokes stay legible.
- Step 3: Pre-process images. Apply deskewing, noise removal and orientation correction before recognition to improve accuracy on low-quality scans.
- Step 4: Configure field extraction. Map each field to its region or label and set the expected data type, such as date, number, PIN code or free text.
- Step 5: Set confidence thresholds. Accept high-confidence fields automatically and route low-confidence fields to a human verifier (human-in-the-loop).
- Step 6: Validate with business rules. Cross-check totals, date formats, PIN codes and ID number formats so obvious errors are caught before data reaches core systems.
- Step 7: Integrate and improve. Push validated output to your ERP, CRM or claims system through the API, and feed corrected fields back to improve future accuracy.
Best Practices
- Start with one high-volume form type, measure field-level accuracy, then expand.
- Use forms with boxed character fields where you control the form design. They noticeably improve handwriting recognition.
- Measure accuracy per field, not per document. A single wrong account number matters more than a misread comment.
- Keep the original image linked to every extracted record for audits and dispute handling.
- Mask sensitive fields such as Aadhaar or account numbers in downstream exports.
Common Mistakes to Avoid
- Scanning at low resolution to save storage, which reduces recognition accuracy.
- Skipping human review entirely for financial or medical fields.
- Testing only on clean samples instead of real, messy production documents.
- Treating ICR output as final without validation rules.
FAQs
What is ICR full form and meaning?
ICR stands for Intelligent Character Recognition. It is an AI-based technology that reads and extracts both handwritten and printed text from documents and converts it into machine-readable data.
How is ICR different from OCR?
OCR (Optical Character Recognition) mainly recognizes printed text using pattern matching, while ICR uses AI and neural networks to also read handwritten text and improve its accuracy over time.
Is ICR accurate for messy or cursive handwriting?
Yes. ICR systems are trained on large, diverse handwriting datasets, allowing them to adapt to different handwriting styles, slants, and minor imperfections with high accuracy.
Which industries use ICR the most?
ICR is widely used in banking, insurance, healthcare, government, and legal sectors to automate the processing of forms, checks, claims, patient records, and legal documents.
Can ICR be integrated via API?
Yes, ICR capabilities can be integrated into existing systems through an API or SDK, enabling automated data extraction from handwritten and printed documents within your own workflows.
What is the cost of ICR per document?
PixDynamics ICR pricing starts from ₹0.50-1 per page, making it the most cost-effective solution in the market. Volume discounts available: 5-10% for 10K+ pages, up to 40% for enterprise contracts. Free trial includes 100 pages.
How fast can ICR process documents?
PixDynamics ICR processes documents in less than 2 seconds per page on average. High-volume batch processing can extract text from 1 million pages per hour. Real-time API processing delivers results in 200-500ms per document.
What is the accuracy rate of PixDynamics ICR?
PixDynamics ICR achieves 99%+ accuracy in character recognition across printed and handwritten text. Accuracy varies by document quality: 99.5%+ for high-quality documents, 95%+ for poor-quality scans. Confidence scores provided for each character.
Is ICR GDPR and ISO 27001 certified?
Yes. PixDynamics ICR is GDPR compliant, ISO 27001 certified, SOC 2 Type II audited, and HIPAA-ready. All document data is encrypted with AES-256. No document retention: processed documents are immediately deleted after extraction. Full compliance audit trails available.
How does ICR compare to manual data entry?
PixDynamics ICR reduces manual data entry by 95%+ while improving accuracy from 85-90% (human) to 99%+ (AI). Processing 10,000 documents: manual entry = 250 hours + ₹2.5L cost, ICR = 10 minutes + ₹5K cost. Payback period: typically 2-4 weeks.
Does ICR support handwritten text and 50+ languages?
Yes. PixDynamics ICR includes advanced handwritten character recognition (HCR) with 95%+ accuracy and supports 50+ languages including English, Hindi, Spanish, French, German, Chinese, Japanese, Korean, Arabic, Portuguese, Russian, and regional languages.
What industries use PixDynamics ICR?
PixDynamics ICR is used by banks, insurance companies, healthcare providers, government agencies, e-commerce platforms, and logistics companies. Common use cases: invoice processing, document digitization, form data extraction, cheque processing, prescription reading, and regulatory compliance.
Can ICR be deployed on-premise?
Yes. PixDynamics ICR supports both cloud and on-premise deployment. Enterprise customers get full source code access, private deployment options, and dedicated infrastructure. Integration takes 2-3 days with 24/7 technical support.
Conclusion
In conclusion, Intelligent Character Recognition (ICR) plays an important role in simplifying and automating various processes across industries. Its ability to convert handwritten and printed text into digital data not only enhances data accuracy but also boosts operational efficiency. Whether in finance, healthcare, legal firms, or other sectors, ICR has proven to be a valuable tool for reducing manual labor and minimizing errors. As businesses continue to embrace digital growth, ICR emerges as a modern technology that empowers organizations to handle data more effectively, ultimately contributing to their success in the industry.
Now that you understand what ICR is, the implementation of ICR technology depends entirely on the specific needs of the company. It's worth noting that OCR is a more cost-effective option in comparison to ICR technology. However, if your company deals with large volumes of daily data processing, encompassing both structured and unstructured documents, adopting a combination of ICR and OCR is a strategic move. This approach not only minimizes the need for manual labor but also ensures high levels of accuracy in the results generated.