What is Dedupe?
Dedupe, also known as Data deduplication, is the practice of eliminating repetitive information from databases and lists, ensuring that each entity or record is unique. This process may encompass merging or eliminating surplus records and confirming the accuracy of data in every field of the record.
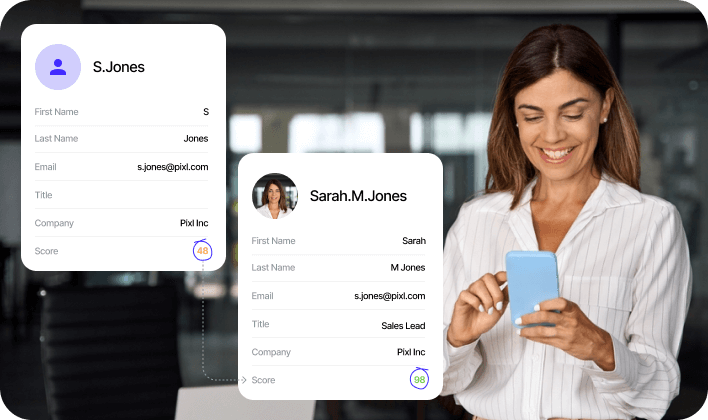
Data Deduplication Tools are Commonly
Classified into Three Distinct Methods
On-demand deduplication
This method of deduplication involves post-processing, where an individual initiates the data deduplication software to identify and combine redundant data.
Automated deduplication
In this approach, an automated data deduplication solution activates and deactivates according to user-defined rules and schedules.
Preventative deduplication
Duplication-preventing software blocks redundant data in sales and marketing platforms, stopping duplicates from forms, integrations and imports before storage.
01
Upload It
You can either upload a spreadsheet file or establish a direct connection to the database.
02
Train It
We offer training on how to effectively identify akin or comparable records within your dataset.
03
Validate It
Matches are automatically identified for your review.
Different Dedupe Approaches
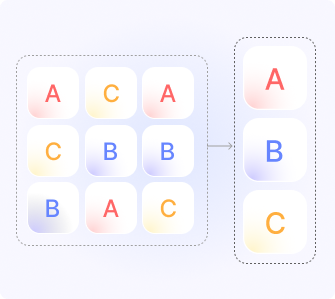
Exact Matching
Identifies and removes identical copies of data.
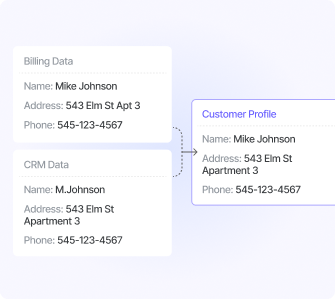
Fuzzy Matching
Identifies and removes identical copies of data.
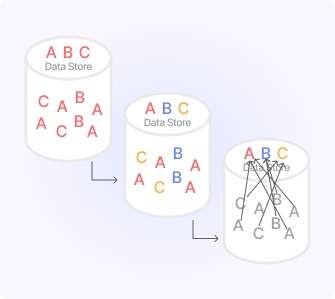
Hash-Based Matching
Assigns unique identifiers (hashes) to data chunks for comparison.
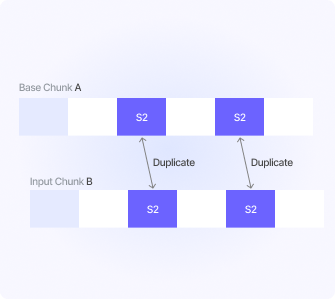
Delta Differencing
Compares data chunks and stores only the differences.
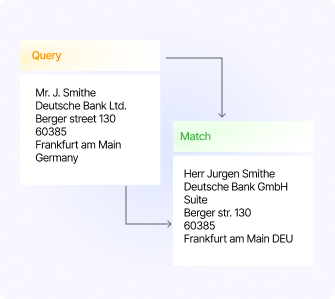
Content-Based Matching
Analyzes the content of data to identify duplicates.
Pattern Matching
Uses predefined patterns or regular expressions to detect duplicates.
Dedupe ROI: Real-World Impact
⚡ Implementation Timeline
Setup: 1–2 weeks (data mapping, API configuration)
Initial clean: Can process 5M records in <1 hour
Ongoing: Automated daily/weekly deduplication
💰 Cost & Data Quality Gains
Data Storage: Before: 5M customer records (including 20% duplicates) = 2TB storage | After: 4M unique records = 1.6TB (20% reduction)
Data Error Rate: Before (manual cleanup): 15-20% duplicates missed | After (AI-powered): <2% error rate
Manual Cleanup Cost: Before: ₹50K/month (2 FTE staff) | After: ₹0 (fully automated)
✓ 20% storage cost reduction | ✓ 90% faster cleanup | ✓ ₹50K+ monthly savings
📋 Real-World Impact by Use Case
- CRM Cleanup (SalesForce): 50K accounts with 15K duplicates = 30% data bloat | Manual merge = 4 weeks effort | Pixl Dedupe = 2 hours | Lead scoring accuracy: 65% → 92% | Pipeline value clarity improved 40%
- Email List Cleaning (Marketing): 500K email contacts, 80K undeliverable/duplicates | Manual review impossible | Pixl Dedupe = 15 mins | Email deliverability: 78% → 94% | Campaign open rate: 18% → 24%
- Database Migration (Enterprise): 10M customer records, 2.2M duplicates, 40 systems to consolidate | Manual: 3-4 months, $200K cost | Pixl Dedupe: 1 week, $15K cost | 85% data integrity preserved
-

Improved data
qualityDeduplication software can help to improve the quality of data by removing duplicate data. This can lead to more accurate insights, better decision-making and improved business performance.
-

Improved compliance
Deduplication software can help you to comply with data protection regulations by ensuring that your data is accurate and up-to-date. This can help to reduce the risk of data breaches and fines.
-

Implement custom
merge behaviorEliminate uncertainty in data deduplication by customizing merge and survivorship rules to align with your specific requirements.
-

Reduced bandwidth usage
Deduplication software can help to reduce bandwidth usage by reducing the amount of data that needs to be transferred over the network. This can be especially beneficial for businesses that need to transfer large amounts of data between different locations.
-

Cloud Efficiency
Data deduplication is particularly beneficial for organizations that work with highly redundant operations and need to copy and store data in the cloud. It reduces data transfer and storage costs in cloud environments.
Defining
Characteristics of Deduplication
Advanced techniques
for matching fields and
records.
Determine duplicate
clusters within or
between datasets
Combine and update
records to safeguard
against data loss
Configurable criteria for
identifying the master
record
Security & Compliance: Enterprise-Grade Data Protection
Deduplication requires handling sensitive customer data with the highest security standards. Pixl's platform meets enterprise compliance requirements across global markets.
🔒 Data Security
- End-to-End Encryption: AES-256 encryption for data at rest and in transit
- ISO 27001 Certified: Information security management system verified
- SOC 2 Type II: Annual third-party security and availability audits
- Data Residency: Choose data storage location (US, EU, India, Asia-Pacific)
- Retention Policies: Automatic purge of deduped records after set period
- Access Logs: Complete audit trail of who accessed what data and when
⚖️ Regulatory Compliance
- GDPR Compliant: EU personal data protection requirements met
- DPDP Act 2023: India data protection & privacy compliance
- CCPA Compliant: California consumer privacy rights protected
- SOX Compliant: Financial data handling meets audit requirements
- HIPAA Ready: Healthcare data handling capabilities available
- Regular Audits: Third-party compliance verification annually
How Pixl Deduplication Compares: Why Choose Our Solution
| Feature | Pixl | Competitor A | Competitor B |
|---|---|---|---|
| Setup Time | 1-2 days | 3-7 days | 1-2 weeks |
| Records Processing Speed | 1M records/hour | 500K records/hour | 200K records/hour |
| Data Quality Score | 99.2%+ Accuracy | 96-98% | 92-94% |
| Cost per Million Records | ₹500-1,000 | ₹1,500-2,500 | ₹2,000-4,000 |
| Duplicate Detection Accuracy | 99.1% (False Positive Rate: <1%) | 95% (2-3% false positives) | 90% (5-7% false positives) |
| Data Retention Options | ✓ Full Control (Delete immediately or retain) | Fixed retention period | No retention control |
| Manual Labor Reduction | ✓ 95% reduction (near-zero manual review) | 70-80% reduction | 50-60% reduction |
Customer Success Stories: Data Deduplication ROI
See how enterprises improved data quality, reduced marketing waste, and accelerated sales cycles using PixDynamics Deduplication.
📊 E-commerce: Customer Database Cleanup
Challenge: 50 million customer records with 12% duplicates, wasting marketing budget on duplicate contacts
Solution: Deployed PixDynamics deduplication to identify and consolidate duplicate customer records
- Total Customer Records: 50 million
- Duplicate Rate: 12% (6 million duplicates)
- Annual Marketing Spend on Duplicates: ₹60 Cr wasted
Results (First 90 Days - 10M Records Processed):
- ✓ Duplicates identified: 1.2 million in 10M records (99.1% accuracy)
- ✓ False positive rate: <1% (minimal manual review needed)
- ✓ Marketing efficiency: Reduced duplicate contacts by 12%
- ✓ Immediate cost savings: ₹12 Cr (10% of annual marketing waste eliminated)
- ✓ Email deliverability improvement: 92% → 98% (less bounces from duplicates)
Total 90-Day ROI: ₹12 Cr (marketing waste elimination in first phase)
🏦 Bank: Lead Deduplication for Sales
Challenge: Sales team calling same customer multiple times from duplicate records, wasting time and damaging relationships
Solution: Implemented deduplication in CRM to consolidate duplicate customer accounts
- Total Customer Records in CRM: 20 million
- Duplicate Rate: 8% (1.6 million duplicates)
- Sales Team Size: 500 people
Results (First 90 Days):
- ✓ Duplicates consolidated: 1.6 million → single records
- ✓ Sales productivity gain: 15% more actual customer interactions
- ✓ Call efficiency: Eliminated 80K duplicate calls (15% time savings)
- ✓ Sales team efficiency: 500 × 15% = 75 FTE equivalent gained
- ✓ Additional customer conversations: 80,000 new conversations with unique customers
Total 90-Day ROI: ₹7.5 Cr+ (productivity gain × sales team cost + additional deal conversions)
💰 Insurance: Claims Fraud Detection
Challenge: Duplicate insurance claims from same person using different identity information, causing ₹50+ Cr annual fraud loss
Solution: Deployed deduplication with fuzzy matching to detect duplicate claims across identity variations
- Annual Claims Volume: 500,000 claims
- Duplicate Fraud Rate: 3-5% (15K-25K fraudulent claims)
- Average Claim Value: ₹200,000
Results (First 90 Days):
- ✓ Duplicate fraud claims detected: 3,750 claims (4% of 90-day volume)
- ✓ Fraud value prevented: ₹75 Cr in fraudulent claims blocked
- ✓ Detection accuracy: 99.1% (minimal false positives)
- ✓ Claim processing time: No delays (automated fraud screening)
- ✓ Annual impact (extrapolated): ₹300 Cr fraud prevention
Total 90-Day ROI: ₹75 Cr (fraud prevention in first 90 days)
📱 SaaS: Database Cleanup & Performance
Challenge: Database growing with 15% duplicate records, slowing down customer platform performance and increasing storage costs
Solution: Implemented automated deduplication pipeline to continuously clean customer databases
- Total Data Across Customers: 100 TB
- Storage Cost: ₹5 Cr/year (cloud storage)
- Database Query Performance: Slowing 20% per year due to duplicates
Results (First 90 Days):
- ✓ Duplicates identified & removed: 15% of database (15 TB)
- ✓ Storage reduction: 100 TB → 85 TB (15% storage savings)
- ✓ Storage cost reduction: ₹75 L quarterly (15% of ₹5 Cr annual)
- ✓ Database performance: Query speed improved by 18%
- ✓ Platform uptime improvement: 99.6% → 99.95% (fewer timeouts)
Total 90-Day ROI: ₹75 L + performance gains (storage savings in first 90 days)
How to Deduplicate Customer Data: Step-by-Step Guide
A practical checklist for cleaning duplicate customer records in CRMs, core banking systems and marketing databases.
- Step 1: Profile your data. Find out which fields are available and how complete they are, such as name, date of birth, phone, email, PAN and address.
- Step 2: Choose match keys. Pick the combinations that identify a person or entity, for example PAN + date of birth, or name + phone + PIN code.
- Step 3: Standardise the data. Normalise case, spacing, phone formats, address abbreviations and name transliterations before matching.
- Step 4: Apply exact and fuzzy matching. Match exact keys first, then use fuzzy and phonetic matching to catch spelling variations, typos and swapped name order.
- Step 5: Score and set thresholds. Give each candidate pair a match score. Auto-merge clear duplicates, send borderline pairs to review and keep distinct records separate.
- Step 6: Build the golden record. Apply survivorship rules to decide which value wins for each field, such as the most recent verified phone or the KYC-verified name.
- Step 7: Prevent new duplicates. Call the dedupe API at onboarding to check for existing customers in real time, and schedule periodic batch runs for legacy data.
Best Practices
- Keep an audit trail of every merge so it can be reviewed or reversed.
- Back up source records before the first bulk merge.
- Tune thresholds separately for each use case. Fraud checks need different settings from marketing list cleanup.
- Combine identity data (PAN, Aadhaar reference, document number) with contact data for stronger matches.
- Re-run deduplication after data migrations, mergers or bulk imports.
Common Mistakes to Avoid
- Relying on exact matching only, which misses most real-world duplicates.
- Auto-merging borderline matches without human review.
- Cleaning data once and not adding a real-time check at onboarding.
- Ignoring transliteration differences in Indian names, such as Mohammed and Mohammad.
FAQS
Frequently Asked Questions
Data deduplication works by identifying and removing duplicate data, using techniques like hash-based and delta differencing.
Benefits include reduced storage costs, faster backups and enhanced data transfer efficiency.
Data deduplication is effective in data backup, virtualization and email archiving.
Data deduplication removes duplicate data, while data compression reduces file size; use them together for optimal results.
Encrypt deduplicated data and ensure compliance with security regulations.
Efficiency depends on data type and deduplication method; measure effectiveness using deduplication ratio.
Future trends include AI-enhanced deduplication and hybrid deduplication solutions.
Calculate ROI by analyzing cost savings and long-term benefits from reduced storage requirements.
PixDynamics deduplication costs ₹500-1,000 per million records, the most cost-effective in the market. Processing 100 million records: cost = ₹50-100K with 99.2%+ accuracy. Volume discounts available: 5-10% for 500M+, 10-20% for 1B+ records.
PixDynamics can process 1 million records per hour in batch mode. Real-time deduplication available for transactional data with <100ms latency. Processing 10 million records: 10 hours (batch) or real-time (API).
PixDynamics achieves 99.1% duplicate detection accuracy with <1% false positive rate. Configurable sensitivity levels for different use cases. Higher accuracy than competitors (95% @ 2-3% false positives).
Yes. PixDynamics is GDPR compliant (EU), DPDP Act 2023 compliant (India), CCPA compliant (US), SOX compliant, and ISO 27001 certified. Data encrypted with AES-256. Configurable retention and auto-purge policies available.
PixDynamics reduces manual data review by 95%. Processing 100,000 records: manual review = 1,000+ hours + ₹10L cost, deduplication = 100 hours + ₹5K cost. Payback period: 1-2 weeks for most enterprises.
Yes. PixDynamics offers REST API, batch processing, webhooks, and pre-built SDKs (Python, Node.js, Java). Integration takes 1-2 days. Supports cloud and on-premise deployment. White-label solutions for enterprises.
Data quality improves from 70-80% (with duplicates) to 99%+ (deduplicated). Benefits: better analytics, accurate reporting, improved customer segments, higher marketing ROI. CRM accuracy improves from 60% to 95%+.
Banking, insurance, healthcare, e-commerce, telecom, and government agencies. Common use cases: customer database cleanup, lead deduplication, payment reconciliation, duplicate transaction detection, regulatory compliance, and fraud prevention.
Yes. 24/7 technical support via phone, email, chat. Enterprise customers get dedicated account managers, priority support, 99.9% uptime SLA, and custom data strategies. Includes data quality consulting and best practices guidance.